Automated checks
32 · 30 pass
23 GraphQL (pytest) + 9 dashboard (Playwright), incl. 2 documented-defect xfails — order-independent, one merged Allure report, CI-validated
I built an independent, risk-based QA framework around a pinned local Saleor environment — a large open-source e-commerce platform I didn't build — documented four defects or candidate issues, and created a cross-browser visual-regression tool using methods from my VFX background.
Portfolio evidence project · Independent QA of Saleor 3.23 (pinned, local) · Point-in-time results · Findings documented, not filed upstream
Automated checks
32 · 30 pass
23 GraphQL (pytest) + 9 dashboard (Playwright), incl. 2 documented-defect xfails — order-independent, one merged Allure report, CI-validated
Documented findings
4 findings
Four defects or candidate issues documented against the pinned local environment; two are backed by strict-xfail regression checks; none has been filed upstream
API under hostile input
0 server errors
an 8-case battery never 500s; query-cost + batch guards hold — reported as genuinely robust
Visual baselines
40
36 across chromium/firefox/webkit + 4 chromium-only i18n baselines; re-runs diff at 0 px
Seeded regression
caught @ 0.01
a 0.2px font-metric drift failed the gate — 5,366 diff px, ratio 0.01 over the 0.005 limit
i18n gap found
1 real gap
“Catalog” / “Fulfillment” render in English across zh-Hans / zh-Hant / ko
I took Saleor — a large open-source commerce platform (Python/Django/GraphQL) I did not build — and set up an independent QA framework around it from the outside. The tests drive the running app through its GraphQL API and admin dashboard without copying or changing Saleor’s own code.
There are two halves. First, a risk-based functional framework — 32 automated checks across API robustness, access control and checkout — which documented four defects or candidate issues in the pinned local environment. Second, a cross-browser visual-regression tool built on methods from my VFX work; it caught a seeded regression and surfaced a localisation gap.
Externally driven against local Saleor 3.23 (pinned prebuilt images). Two lanes — pytest (GraphQL) and Playwright (dashboard + axe) — emit one merged Allure report in CI; the visual suite runs on its own config. Everything below maps to an artifact in the repo: the risk-based test plan, traceability and coverage maps, four drafted bug reports, and the perceptual-diffing write-up.
I started with a risk-first plan: score 14 areas by how likely a problem is and how much it would hurt. Money movement and access control came out on top, with i18n, visual regression and accessibility treated as first-class lanes. Four probes carry the weight of the functional suite.
An 8-case hostile-input battery (invalid ids and enums, first-argument extremes, deeply nested and aliased queries) never returns a 500 — every failure is a typed GraphQL error. Query-cost and batch-size guards hold. Where Saleor was robust I reported it as robust, and locked that in as passing tests rather than inventing a bug.
A MANAGE_ORDERS-only App token proves the permission boundary — it can read orders but cannot create products — without brittle staff-invite flows. Anonymous-vs-staff gating and tokenCreate (valid and bad-credential) are covered alongside it.
No storefront ships in saleor-platform, so the customer journey is exercised through the API: checkoutCreate → add line → address → delivery method → totals, with each checkout, product and scoped App created and torn down inside its own test.
Expected results come from the running app. A negative-input test asserts the real HTTP 400 validation contract — upstream research had predicted 200; the live app disagreed, and grounding the test in the system caught the discrepancy.
A structured exploratory session produced four evidence-backed finding reports against a pinned local Saleor 3.23 environment. They are portfolio findings, not upstream-confirmed defects, and none has been filed upstream; de-duplication and Saleor’s CLA or security-disclosure process would come first.
Public updateMetadata on a Checkout maps to no_permissions, so an unauthenticated client accepted a 1 MB value, 2,000 keys and a 100,000-char key with no error — a low-effort storage/DoS vector. A strict-xfail regression asserts the desired 100-item cap and will alert when a limit lands.
Relates to Saleor #19210 · reproduced (full) · strict-xfail
checkoutLinesAdd accepted 73 distinct variant lines in one call (bounded only by the seeded catalog) and a CheckoutLine took a 1 MB metadata value — while per-line quantity is correctly capped at 50. A second strict-xfail locks in the desired list-size cap.
Relates to Saleor #19209 · reproduced (full) · strict-xfail
An axe-core gate found 12 icon buttons with no accessible name, a missing document lang, disabled pinch-zoom and 5 sub-AA contrast nodes on the product-create form. The high-confidence items lead; framework-generated ARIA-role nodes are flagged for manual triage before filing.
New finding · axe evidence · de-dupe before filing
get_client_ip trusts the leftmost, client-supplied X-Forwarded-For value, so the per-IP login-throttle key is attacker-controlled and can be rotated. Source-verified against 3.23.5 and throttle-confirmed live; a clean end-to-end spoof needs a proxied deployment, so this is a partial (source-verified) repro, not a full local exploit.
Relates to Saleor #19203 · source-verified · security disclosure
A neat side effect: my own repeated tokenCreate probing tripped Saleor’s per-IP login throttle (LOGIN_ATTEMPT_DELAYED). Rather than fight it, I had the E2E suite log in once into a shared storageState and the API fixtures retry the throttle — a real testability constraint that shaped the harness’s auth-reuse architecture.
Taking the screenshots is the easy part. A visual-regression suite is only worth anything if it fails when — and only when — a human would call it a regression, not on rendering noise, font jitter or a redrawn timestamp. The real deliverable is that judgment; the baselines and the caught-regression image follow from it.
40 committed baselines: three dense admin screens (product editor, configuration, order detail) × desktop 1280×800 + mobile 375×812 × light + dark × chromium/firefox/webkit, plus a 4-locale i18n pass. It fills the gap saleor-dashboard’s own setup leaves — Chrome-only, no baselines, no Firefox/WebKit, no mobile.
Fixed deviceScaleFactor and viewport, animations and caret off, document.fonts.ready awaited, timezone/locale pinned to UTC/en-US, theme + UI locale set in localStorage before the first navigation, and dynamic regions (ids, dates, money, addresses) masked. The payoff: back-to-back clean runs diff at 0 pixels, which is what lets the gate be tight.
pixelmatch is the zero-dependency default; SSIM is the documented upgrade if gamma/AA drift the determinism levers can’t remove ever appears; odiff is the swap when suite runtime matters; and a managed service (Argos / Percy / Lost Pixel) for side-by-side PR review is a reporter change, not a rewrite.
In film VFX, I worked on pixel-level QC — deciding what pixel difference is a defect versus what is the medium’s noise floor. This toolkit automates exactly that judgment for web UIs.
Playwright’s toHaveScreenshot exposes two independent tolerances, and they have opposite blind spots. A 3° hue-rotate across the whole page passed at threshold 0.15 — every pixel’s YIQ delta stayed under the per-pixel threshold, so pixelmatch counted zero different pixels. A 1px shift of headings alone also passed — too few pixels to cross the ratio. The regression that reliably failed was a 0.2px letter-spacing drift: it moves every glyph edge, lighting up ~1% of a text-dense screen (ratio 0.01, over the 0.005 gate). To catch colour drift you must lower threshold; to catch layout shifts you must lower the ratio and prefer text-dense targets. That interaction is the core methodology lesson.
To prove the gate still bites, I inject a subtle font-metric + colour + 1px drift into the product editor — the densest screen — and re-run the suite. It fails as designed at 5,366 diff pixels (ratio 0.01, over the 0.005 gate), flagging every shifted label on the form.
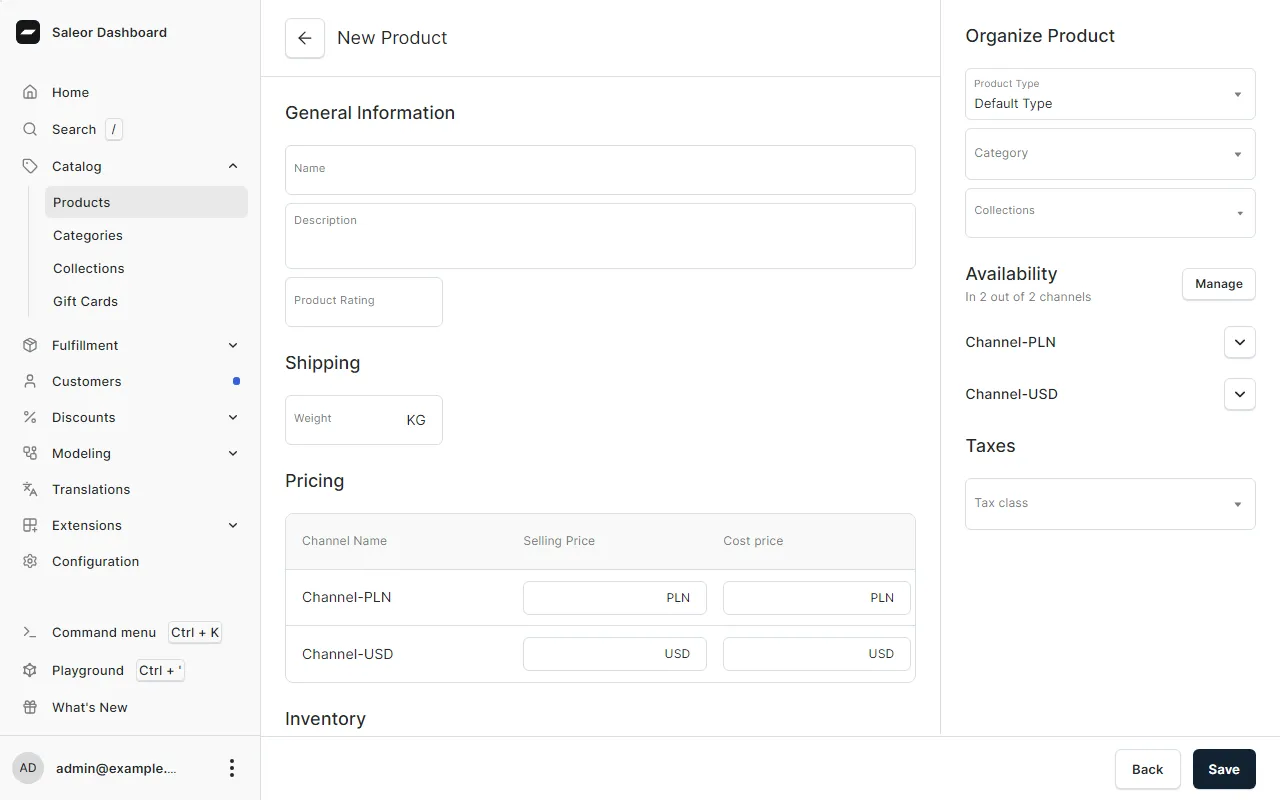
I show the clean baseline here rather than the raw pixelmatch diff. A diff frame is a dimmed, false-colour overlay of only the changed pixels — it reads as visual noise out of its side-by-side context — so the load-bearing evidence is the number the gate acts on, the 5,366-pixel (ratio 0.01) failure above, not the picture. That is what turned the build red.
The same locale pass turned up a genuine finding: “Catalog” and “Fulfillment” render in English across all of zh-Hans, zh-Hant and ko, and “Translations” stays English under zh-Hans and ko — captured as per-locale baselines and a logged label report. No clipping or overflow at these widths. It is a dashboard translation-completeness gap (to dedupe upstream before filing), not a layout bug — a QA parity finding, not a fabricated one.
The framework drives a local, pinned Saleor 3.23 environment, so every result is point-in-time against that build. Four defects or candidate issues are documented in draft reports, but none has been submitted or confirmed upstream; de-duplication plus Saleor’s CLA or security-disclosure process would come first. BR-004 is source-reviewed and throttle-confirmed rather than a full local exploit. Under a hostile-input battery, the API produced no 500s and its cost and batch limits held, which I reported as a positive result.
Safest reading: independent, risk-based QA stood up around an unfamiliar production codebase — a working framework, four documented defects or candidate issues, and a perceptual-diffing toolkit with a caught seeded regression — not a security audit or an upstream contribution record.
De-duplicate and file the drafted reports through Saleor’s process (the security-disclosure route for the X-Forwarded-For finding); extend the API lane to voucher and payment concurrency and the order-fulfilment state machine; bootstrap Linux CI baselines inside the pinned Playwright image and tighten the gate toward 0.1 / 0.001 per screen as determinism is proven; and seed real translations to turn the i18n probe into a full locale matrix.
Framed as external, risk-based QA of an unfamiliar system — ISTQB-style test design, ITIL-adjacent defect reporting, and a perceptual-diffing methodology carried over from VFX compositing.
The risk-based plan, the traceability and coverage maps, the four drafted bug reports, the merged Allure report, and the visual-regression toolkit with its seeded-regression evidence all live in the repo. Ask for a walkthrough or a read-only look at the reports.
Request a walkthrough